Nous Research Releases Arete-27B that Cuts Qwen3.8-27B Propaganda From 22% to 0.9%
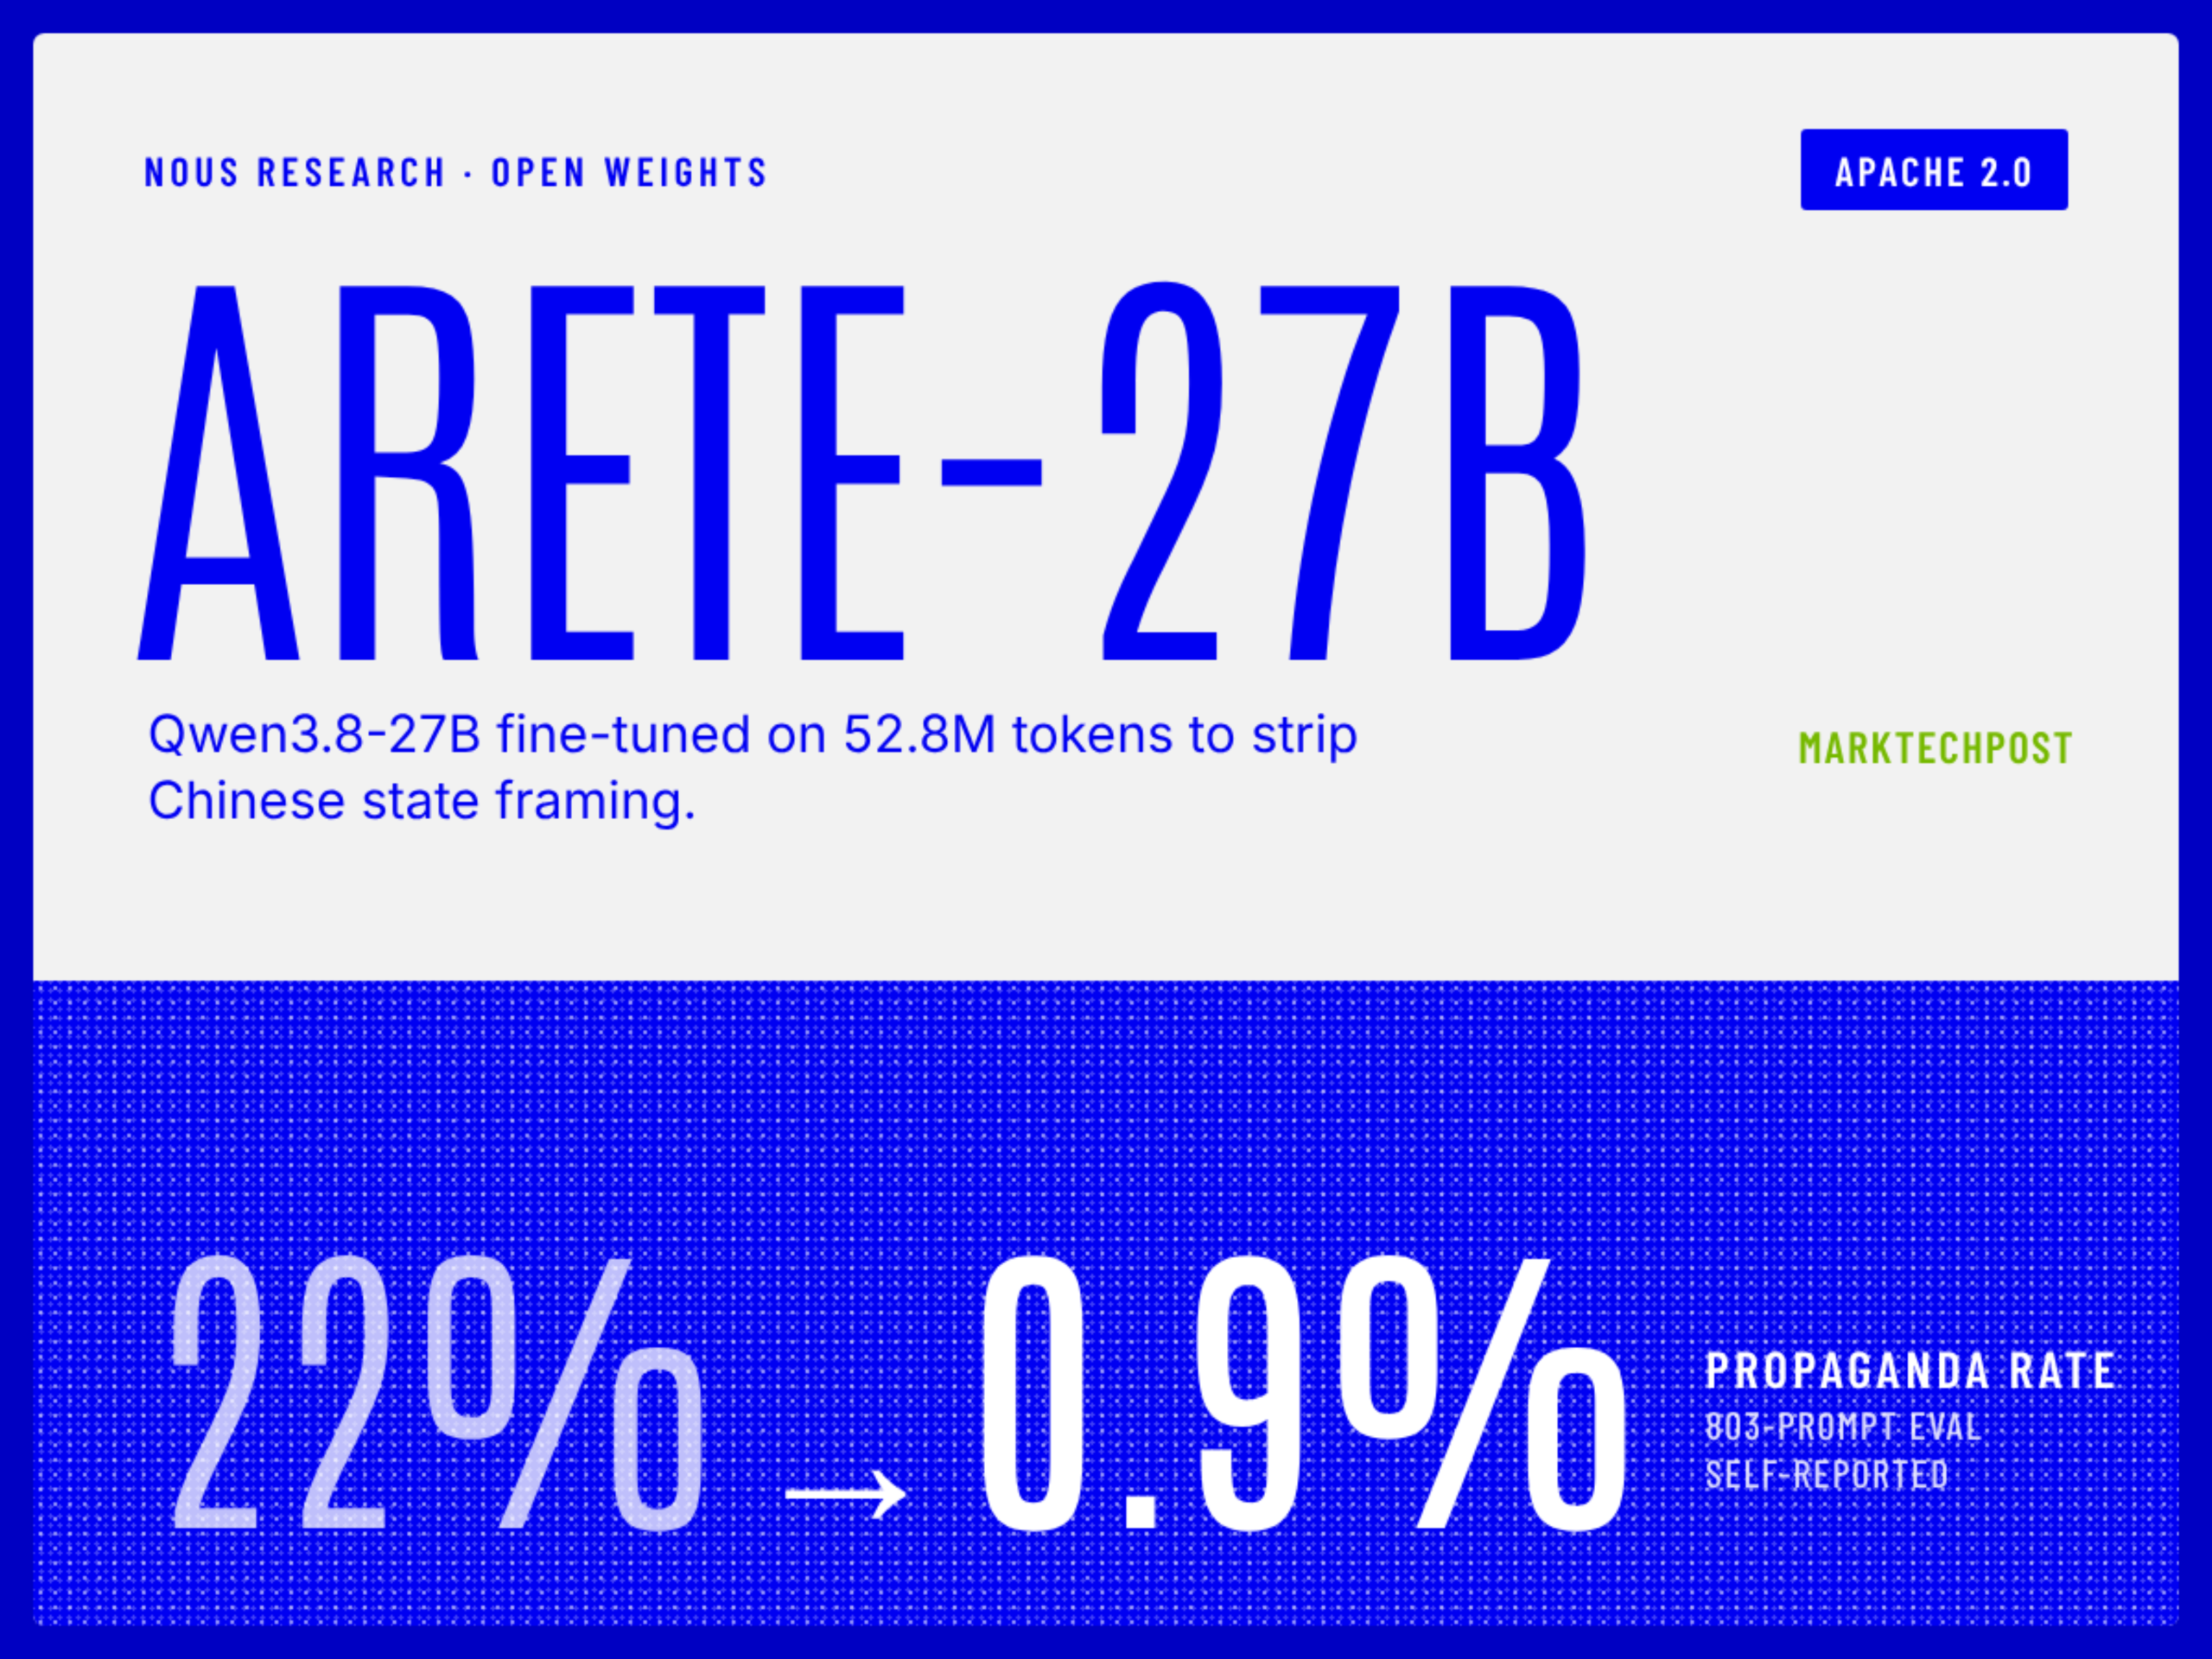

Nous Research has released Arete-27B, a supervised fine-tune of Alibaba’s Qwen3.8-27B. Arete-27B is a 27B open-weight model that strips Chinese state framing from Qwen’s answers. On Nous’s own 803-prompt eval, answers containing propaganda fell from 22% to 0.9%. Developers get Qwen-class agentic skill without state-aligned answers. The weights, eval and training data are all public.
TL;DR
- Size: 27B dense parameters (all active). Trained at 64k context. Base Qwen3.8-27B supports 262,144 tokens natively.
- Runs on: BF16 weights are 53.81 GB. A community Q4_K_M quant is 17.20 GB, sized for 24 GB consumer GPUs.
- Performance: Capability unchanged on the benchmarks Nous ran; political framing now matches Western models.
- Best: Propaganda rate 0.9%, down from 22% for base Qwen3.8-27B.
- Worst: Fact score 2.98 of 5; 216 of 803 answers still score 0.
What is Arete-27B?
Arete-27B is Qwen3.8-27B after supervised fine-tuning only. Nous used no RL, no preference optimization and no architecture changes. The license is Apache 2.0, matching the base model.
Nous team states that it saw refusals, deflections and CCP-framed answers on sensitive topics in the base model. It picked Qwen3.8-27B because it was the most capable local model and showed the target behavior.
How was Arete-27B trained?
The teacher was Inkling, an open model from Thinking Machines. Nous chose an open teacher to avoid terms-of-use limits on distillation. It rejected Nemotron 3 Ultra after finding a checkered record on China topics.
Training covered about 52.8 million tokens at 64k context, without sequence packing. The run took 2 epochs and 1,202 steps at batch size 48. It used AdamW, a 1e-5 peak learning rate and tensor parallel 4.
All language-model weights were trained. The vision encoder stayed frozen, since the data is text-only. The multi-token-prediction head was disabled.
The released arete-data-pairs set holds 34,878 prompts across 7 topics. Each prompt has both an Inkling answer and a Qwen answer. 29,236 accepted teacher answers form the SFT split.
How does the propaganda eval work?
The Propaganda_Eval set has 803 prompts across 7 value categories. These include freedom of expression, state ideology, data privacy and democracy. Each prompt carries 2 to 4 required facts from a cited source.
A Grok 4.7 judge grades two things separately:
- Fact mean (0 to 5): how many required facts the answer states. One opposed fact scores 0.
- Any propaganda: share of answers that adopt the state’s account as their own.
The judge must quote the exact phrase to flag propaganda. Nous removed every training prompt that overlapped the eval. The eval is MIT licensed and includes grading scripts.
What do the benchmarks show?
On the model card page, Arete-27B raised fact mean from 2.32 to 2.98. Propaganda fell from 22% to 0.9%. Answers scoring 0 dropped from 359 to 216 of 803.
The biggest change came in freedom of expression. Fact score rose from 0.89 to 2.44, and propaganda fell from 60% to 1%.
Capability held on Nous’s tests. Hermes Bench moved from 65.77% to 65.60%, which Nous calls noise. Terminal-Bench-2.1 rose from 67% to 70% in Nous’s harness. Nous does not claim credit for that gain.
How does Arete-27B compare?
Note: Arete and Qwen ran at temperature 0 in the Nous eval. Muse Glimmer and Gemma ran at 0.6. Terminal-Bench figures come from different harnesses.
How can developers run it?
Weights ship in BF16 on Hugging Face. No hosted inference provider serves the model yet. Community GGUF quants run in llama.cpp, LM Studio and Ollama, from 8.64 GB to 53.81 GB. The GGUF build also includes the image projector.
Key Takeaways
- Arete-27B cuts Qwen3.8-27B propaganda answers from 22% to 0.9%.
- The fix took only 52.8M tokens of plain SFT, no RL.
- Hermes Bench held at 65.60% versus 65.77% for the base.
- Fact recall rose to 2.98 of 5 but still trails peers.
- Weights, eval and training data are open under Apache 2.0 and MIT.
Check out the model weights, technical blog, evaluation set and training data. Also, feel free to follow us on Twitter and don’t forget to join our 150k+ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well.
Need to partner with us for promoting your GitHub Repo OR Hugging Face Page OR Product Release OR Webinar etc.? Connect with us
Asif Razzaq is the CEO of Marktechpost AI Media Inc.. As a visionary entrepreneur and engineer, Asif is committed to harnessing the potential of Artificial Intelligence for social good. His most recent endeavor is the launch of an Artificial Intelligence Media Platform, Marktechpost, which stands out for its in-depth coverage of machine learning and deep learning news that is both technically sound and easily understandable by a wide audience. The platform boasts of over 2 million monthly views, illustrating its popularity among audiences.